
Ask the Part 4 version of Nimbus this:
"I was charged twice for order #1043. Can I get my money back?"
It checks eligibility, sees the order is 20 days old, and replies: "Sorry, refunds are only possible within 14 days."
That’s wrong. Nimbus’s own refund policy, the document we indexed in the RAG series, says:
"Duplicate charges are always refunded in full, regardless of the 14-day window."
The agent can act, but it has lost everything the RAG bot knew. The RAG bot knew the policy but couldn’t act. In this part we combine them: the RAG search becomes one of the agent’s tools, so Nimbus can read the policy and act on orders in the same conversation. This pattern is often called agentic RAG, and we’ll build it in plain PHP and MySQL with the code you already have.
Before you start
- What you’ll build: a
search_help_centertool built from RAG Episode 5’s retrieval, added to the agent from Part 4.- You need: the setup from Part 4. Having done the RAG series helps, but all the RAG code you need is included in this part’s folder.
- Code for this part: GitHub →
part-05🔀 Gemini or OpenAI? The code for this series comes in two versions:
Gemini Setup(free tier, recommended for learning) andOpenAI Setup(paid). The agent logic is the same in both. Only the small layer that talks to the AI provider differs, because each provider formats tool calls slightly differently, so the code may vary a bit between the two. Model names and free-tier limits change often: check.env.examplefor the current defaults.
Fixed RAG vs agentic RAG
A quick reminder of the terms from the RAG series:
- Embedding: a list of numbers that represents the meaning of a piece of text. Texts with similar meanings get similar numbers.
- Retrieval: turning the question into an embedding and finding the stored passages (chunks) whose embeddings are closest.
- Similarity score: how close a chunk is to the question, from 0 (unrelated) to 1 (same meaning). We ignore chunks below a minimum score.
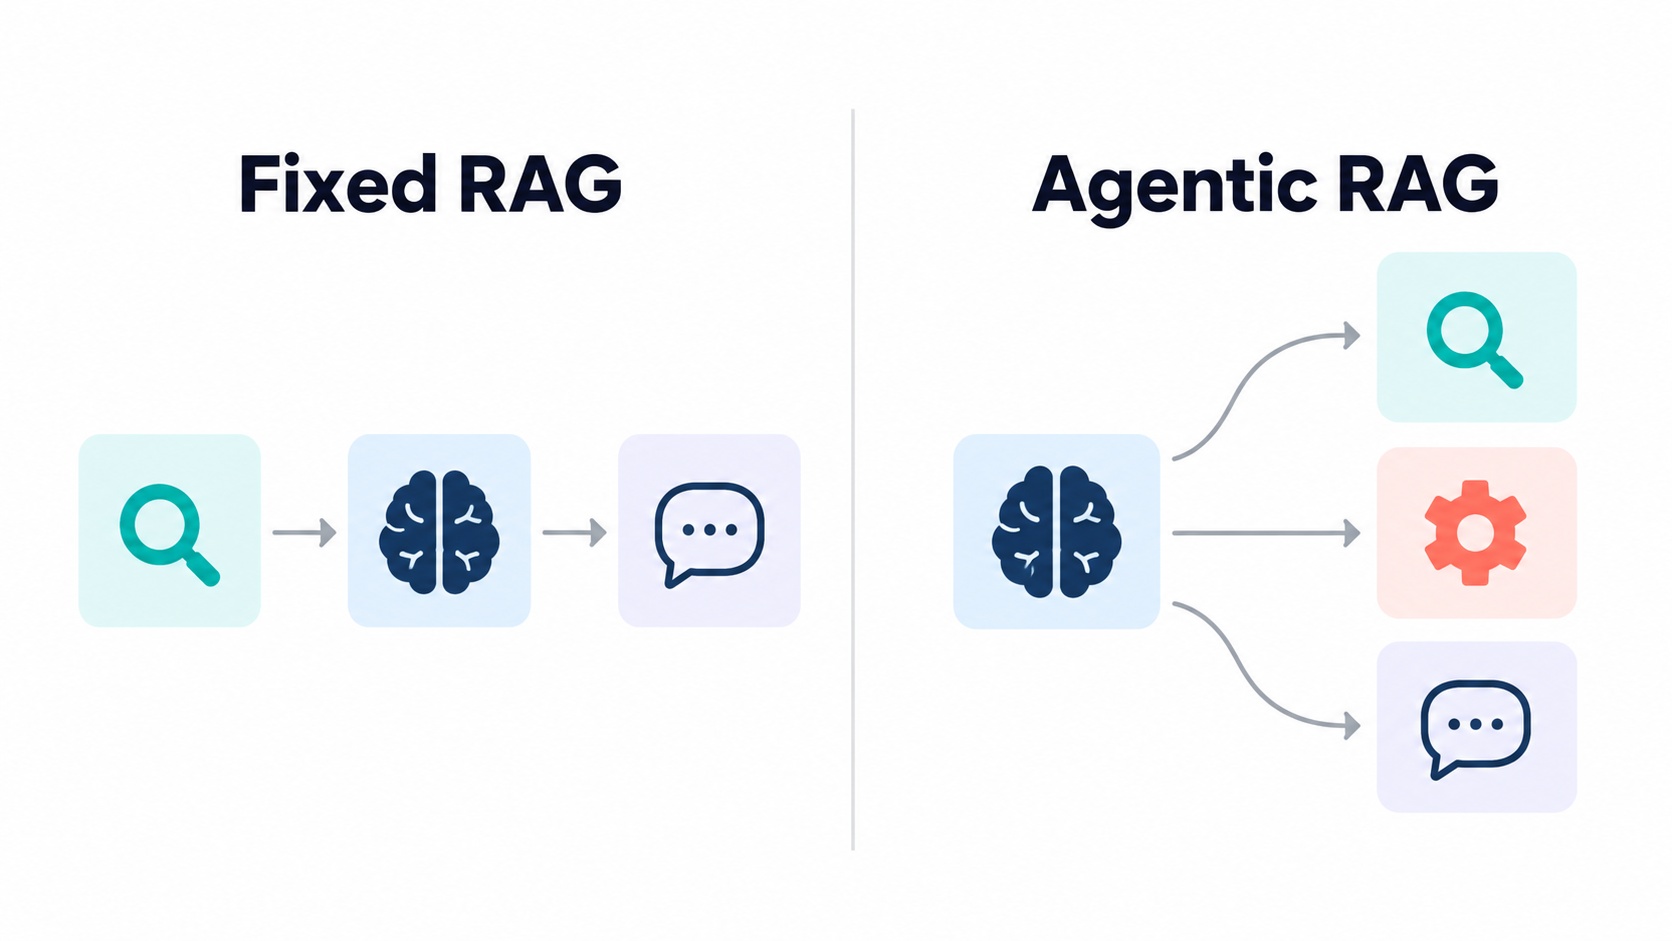
In the RAG series, retrieval ran every time, before the model saw the question. That’s fixed RAG: search first, always, then answer.
In an agent, retrieval becomes a tool. The model decides whether to search, what to search for, and when, just as it decides when to look up an order. That’s agentic RAG.
| Fixed RAG (RAG series) | Agentic RAG (this part) | |
|---|---|---|
| When it searches | Before every answer | When the model decides it needs to |
| What it searches for | The customer’s exact words | A search phrase the model writes |
| "What’s the status of order 1042?" | Searches the docs anyway, finds nothing useful | Uses lookup_order, doesn’t search |
| "Charged twice, refund?" | Finds the policy, but can’t check the order | Checks the order and searches the policy |
| Can search twice with different words | No | Yes, within the step limit |
Agentic RAG costs an extra model decision, but it uses the right source for each question and can combine them.
Build it
The part-05 folder brings together two codebases:
- From Part 4: the loop, the order tools, tickets, traces and the provider adapter (
llm.php), all unchanged. - From the RAG series (Episode 6): the knowledge base (
knowledge-base/*.md),loader.php,chunker.php,ingest.php,vector.php,functions.sql(thedot_product()MySQL function) andbuild-index.php.
Step 1: Set up the database and the index
The schema now also creates the chunks table from the RAG series. Then we load the dot_product() function, seed the orders, and build the search index:
cd part-05
mysql -u root -p < schema.sql      # customers, orders, tickets + chunks
mysql -u root -p < functions.sql   # dot_product() from the RAG series
mysql -u root -p < seed.sql
php ingest.php                     # knowledge-base/*.md → chunks.json
php build-index.php                # embeds each chunk and stores it in MySQL
⚠️ Gotcha: This uses the same
nimbusdatabase as the RAG series and recreates itschunkstable. If you go back to the RAG code later, run itsbuild-index.phpagain. Also don’t mix providers: Gemini and OpenAI embeddings have different sizes, so an index built with one can’t be searched with the other.
Add the new settings from .env.example to your .env if you created it before this part: the embedding model and RAG_MIN_SCORE, the minimum similarity score.
🔀 Provider difference:
embed.phpis provider-specific, exactly as in the RAG series: Gemini’sembedContentendpoint (768-dimension vectors by default) or OpenAI’sembeddingsendpoint (1536 dimensions). The only change is that both now send requests through Part 4’shttpPostJson(), so building the index gets automatic retries on the free tier.
Gemini (Gemini Setup/part-05/embed.php):
<?php
// embed.php — turn a string into an embedding vector (Google Gemini).
// Same as the RAG series, but sent through httpPostJson() so it gets retries.
require_once __DIR__ . '/llm.php';

function getEmbedding(string $text): array {
    $model = env('GEMINI_EMBED_MODEL', 'gemini-embedding-001');
    $data  = httpPostJson(
        'https://generativelanguage.googleapis.com/v1beta/models/' . $model . ':embedContent',
        ['Content-Type: application/json', 'x-goog-api-key: ' . env('GEMINI_API_KEY')],
        [
            'model'                => 'models/' . $model,
            'content'              => ['parts' => [['text' => $text]]],
            // Smaller vectors are cheaper to store. Documents and questions use the
            // same setting, so their vectors stay comparable.
            'outputDimensionality' => (int) env('GEMINI_EMBED_DIM', '768'),
        ]
    );
    return $data['embedding']['values']
        ?? throw new RuntimeException('No embedding returned: ' . json_encode($data));
}
OpenAI (OpenAI Setup/part-05/embed.php):
<?php
// embed.php — turn a string into an embedding vector (OpenAI).
// Same as the RAG series, but sent through httpPostJson() so it gets retries.
require_once __DIR__ . '/llm.php';

function getEmbedding(string $text): array {
    $data = httpPostJson(
        'https://api.openai.com/v1/embeddings',
        ['Content-Type: application/json', 'Authorization: Bearer ' . env('OPENAI_API_KEY')],
        ['model' => env('OPENAI_EMBED_MODEL', 'text-embedding-3-small'), 'input' => $text]
    );
    return $data['data'][0]['embedding']
        ?? throw new RuntimeException('No embedding returned: ' . json_encode($data));
}
Step 2: Retrieval as a function the agent can call
knowledge.php is RAG Episode 5’s retrieve() function, almost line for line, renamed to searchHelpCenter():
<?php
// knowledge.php — search the help center. This is RAG Episode 5's retrieve(),
// now used as a TOOL: the agent decides when to search.
// Needs db.php, embed.php and vector.php loaded first.

function searchHelpCenter(string $query, array $options = []): array {
    $topK         = $options['top_k']          ?? 4;
    $minScore     = $options['min_score']      ?? (float) env('RAG_MIN_SCORE', '0.27');
    $maxPerSource = $options['max_per_source'] ?? 2;
    $maxChars     = $options['max_chars']      ?? 4000;

    $queryVec = normalize(getEmbedding($query));

    // Fetch a few extra candidates so the per-source cap has room to work.
    $stmt = db()->prepare(
        'SELECT source, title, content,
                dot_product(embedding, CAST(:qvec AS JSON)) AS score
           FROM chunks
         HAVING score >= :min_score
          ORDER BY score DESC
          LIMIT :k'
    );
    $stmt->bindValue(':qvec', json_encode($queryVec));
    $stmt->bindValue(':min_score', $minScore);
    $stmt->bindValue(':k', $topK * 3, PDO::PARAM_INT);
    $stmt->execute();

    $results   = [];
    $perSource = [];
    $charsUsed = 0;

    foreach ($stmt->fetchAll() as $row) {
        $src = $row['source'];
        if (($perSource[$src] ?? 0) >= $maxPerSource) {
            continue;                                   // don't let one document dominate
        }
        if ($charsUsed + mb_strlen($row['content']) > $maxChars) {
            continue;                                   // keep the tool result small
        }
        $results[] = [
            'source'  => $src,
            'content' => $row['content'],
            'score'   => round((float) $row['score'], 3),
        ];
        $perSource[$src] = ($perSource[$src] ?? 0) + 1;
        $charsUsed      += mb_strlen($row['content']);
        if (count($results) >= $topK) {
            break;
        }
    }
    return $results;                                    // empty = nothing relevant
}
Two small changes from the RAG version:
- The minimum score comes from
.env(RAG_MIN_SCORE). Gemini and OpenAI embeddings produce different score ranges, so one fixed number doesn’t suit both. Start with0.27; if good passages are missed or unrelated ones get through, tune it with thecalibrate.phpscript from RAG Episode 5. - Each result returns only
source,contentandscore. Everything we return goes into the conversation history and is resent on every step of the loop, so we keep tool results lean.
Step 3: Add the search tool
The new definition goes at the end of toolDefinitions(), and a new case goes in runTool():
// part-05/tools.php (excerpt: the new definition)
        [
            'name'        => 'search_help_center',
            'description' => 'Search the Nimbus help center (refund policy and its exceptions, '
                           . 'FAQ, getting-started guide). Use it for questions about how '
                           . 'Nimbus works or what a policy says, and whenever a customer '
                           . 'mentions a situation the other tools may not cover, such as '
                           . 'a duplicate charge. Returns matching passages with their '
                           . 'source file. Do NOT use it for data about a specific order.',
            'parameters'  => [
                'type'       => 'object',
                'properties' => [
                    'query' => [
                        'type'        => 'string',
                        'description' => 'A short search phrase in plain words, '
                                       . 'e.g. "refund for duplicate charge"',
                    ],
                ],
                'required'   => ['query'],
            ],
// part-05/tools.php (excerpt: the new case in runTool)
        case 'search_help_center':
            $query = trim((string) ($args['query'] ?? ''));
            if ($query === '') {
                return ['error' => 'query is empty'];
            }
            $results = searchHelpCenter($query);
            return $results
                ? ['results' => $results]
                : ['results' => [], 'note' => 'Nothing relevant found in the help center.'];
Look at the description. It says what the tool covers (refund policy and its exceptions, FAQ, getting started), when to use it (how Nimbus works, what a policy says, situations the other tools may not cover, such as a duplicate charge), and when not to (data about a specific order).
The query parameter is a search phrase the model writes, not the customer’s message. A customer might write three angry sentences; the model searches for "refund for duplicate charge", which matches the policy much better.
When nothing passes the minimum score, the tool says so explicitly ("Nothing relevant found"). This is RAG Episode 6’s "I don’t know" rule, now enforced through a tool result.
Step 4: Teach the agent which source to trust
The loop in agent.php is unchanged from Part 4. Only the system prompt changes:
// part-05/agent.php (excerpt)
const SYSTEM_PROMPT = <<<TXT
You are Nimbus HelpDesk AI, the support assistant for Nimbus, a project-management SaaS.
Use the available tools whenever you need real data. Never guess order details,
dates, policies or refund decisions: the tools are the source of truth.

Questions about how Nimbus works or what a policy says: search the help center and
answer only from what it returns. Cite the source file in brackets, e.g. [faq.md].
If the search finds nothing relevant, say you don't know and offer to open a ticket.

Requests about a specific order: use the order tools. If the customer hasn't given
an order number and you need one, ask for it. Never invent one.

Refunds: you cannot issue refunds yourself. Check eligibility first. If eligible,
open a refund ticket. If not eligible, search the help center for exceptions that
match the customer's situation (for example, duplicate charges) before saying no.
If an exception applies, open a billing ticket that explains it; the team decides.
After opening a ticket, always give the customer the ticket number.

If a tool returns an error, don't retry it blindly: explain the problem or ask the customer.
Keep answers brief and friendly.
TXT;
It’s longer than before, so it’s split into paragraphs by situation. Two of them carry the main ideas of this part:
- "Answer only from what it returns. Cite the source file in brackets." This is the grounding rule from the RAG series. Citations still work because each tool result includes its
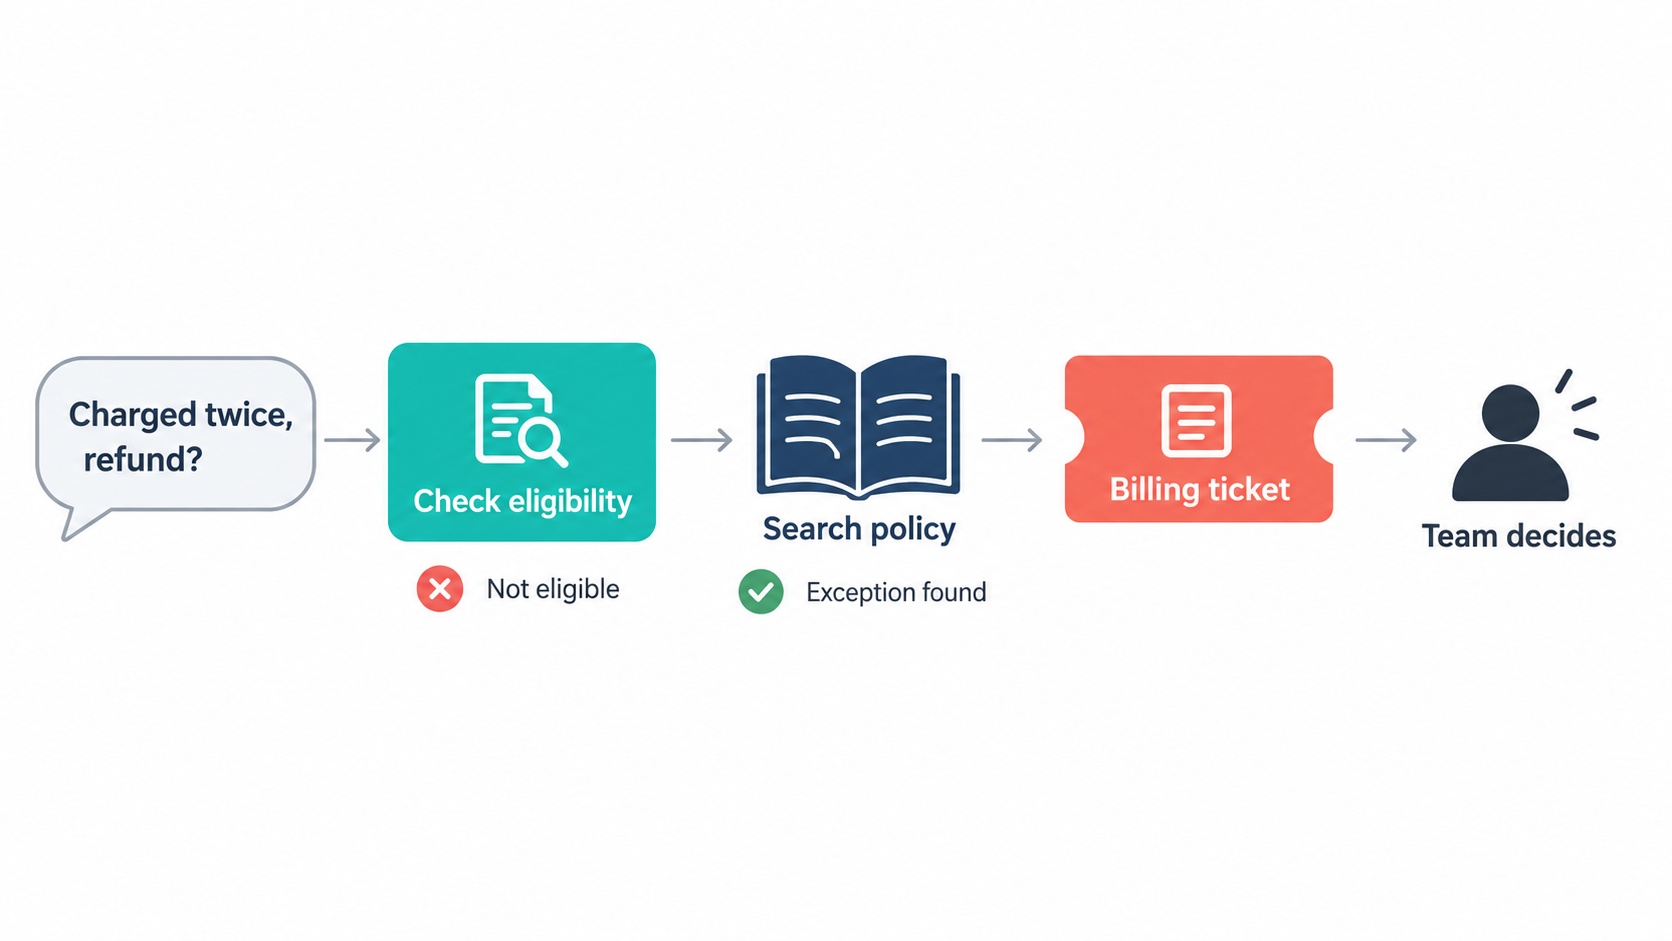
source. - "If not eligible, search the help center for exceptions … before saying no. If an exception applies, open a billing ticket … the team decides." This connects the two sources: the eligibility tool still enforces the standard 14-day rule; the knowledge base can reveal a documented exception; and a human decides the exception through a ticket.
Prompt spotlight: rules, exceptions and who decides
This part introduces a pattern you’ll reuse in every serious agent:
| Layer | Where it lives | Example | Can the model override it? |
|---|---|---|---|
| Standard rule | PHP code (a tool) | 14-day refund window | No |
| Documented exceptions | Knowledge base (search tool) | Duplicate charges always refunded | No, it can only find them |
| Decision on an exception | A human, via a ticket | Approve the duplicate-charge refund | No |
| Conversation | The model | Explaining, asking, summarising | Yes, that’s its job |
The model never decides that an exception applies to money. It finds the rule, finds the exception, gathers the facts, and hands a well-written ticket to a person. Part 7 adds the next layer: human approval inside the agent for risky actions.
💡 Tip: Policies change. With the exception in the knowledge base rather than in code, updating it means editing
refund-policy.mdand runningingest.phpandbuild-index.phpagain. No PHP changes.
Try it
A pure documentation question. Only the search tool runs:
php ask-agent.php "Do you offer a free trial?"
  [step 1] model → search_help_center({"query":"free trial"}) (742 ms)
  [step 1] PHP  ← {"results":[{"source":"faq.md","content":"Nimbus FAQ\n\nHow do I reset my password? ...Do you offer a free trial? Yes - every new account includes a 14-day free trial, no credit card required. ...","score":0.612}]}
  [step 2] model answered (655 ms)
  [done] outcome: answered · run_id: 20261021-141203-1a2b3c
Yes! Every new account includes a 14-day free trial, and no credit card is required. [faq.md]
Docs and order data in one question:
php ask-agent.php "What's your refund policy, and can I get one for order 1042?"
  [step 1] model → search_help_center({"query":"refund policy"}) (901 ms)
  [step 1] PHP  ← {"results":[{"source":"refund-policy.md",...},{"source":"faq.md",...}]}
  [step 1] model → check_refund_eligibility({"order_id":1042}) (901 ms)
  [step 1] PHP  ← {...,"eligible":true,...}
  [step 2] model → create_support_ticket({"category":"refund","summary":"Refund request for order 1042, eligible (3 days old).","order_id":1042}) (980 ms)
  [step 2] PHP  ← {"created":true,"ticket_id":5001,"status":"open"}
  [step 3] model answered (700 ms)
Our policy offers a full refund within 14 days of purchase [refund-policy.md].
Order #1042 qualifies, so I've opened ticket #5001 for your refund.
The case that failed at the top of this post:
php ask-agent.php "I was charged twice for order #1043. Can I get my money back?"
  [step 1] model → check_refund_eligibility({"order_id":1043}) (810 ms)
  [step 1] PHP  ← {...,"days_since_purchase":20,"eligible":false,"reason":"Purchased 20 days ago; refunds are only possible within 14 days."}
  [step 2] model → search_help_center({"query":"refund duplicate charge"}) (870 ms)
  [step 2] PHP  ← {"results":[{"source":"refund-policy.md","content":"...Duplicate charges are always refunded in full, regardless of the 14-day window. ...","score":0.703}]}
  [step 3] model → create_support_ticket({"category":"billing","summary":"Customer reports a duplicate charge on order 1043 (Starter monthly, $12). Outside the 14-day window, but the policy says duplicate charges are always refunded.","order_id":1043}) (1020 ms)
  [step 3] PHP  ← {"created":true,"ticket_id":5002,"status":"open"}
  [step 4] model answered (690 ms)
Order #1043 is outside our usual 14-day refund window, but duplicate charges are
always refunded in full [refund-policy.md]. I've opened ticket #5002 so our billing
team can reverse the extra charge.
Four steps: the rule, the exception, the hand-off, and an answer with a citation and a ticket number.
And a question the knowledge base can’t answer:
php ask-agent.php "What's the weather in Mumbai?"
  [step 1] model → search_help_center({"query":"weather Mumbai"}) (720 ms)
  [step 1] PHP  ← {"results":[],"note":"Nothing relevant found in the help center."}
  [step 2] model answered (610 ms)
Sorry, I can only help with questions about Nimbus. I don't have weather information.
💡 Tip (Gemini free tier): building the index uses one request per chunk, and the duplicate-charge example uses about five model and embedding calls. If you hit a
429,httpPostJson()retries automatically; if it keeps failing, switch to a Flash-Lite chat model.
Recap
- Agentic RAG turns retrieval into a tool. The model decides when to search, what to search for, and how to combine the results with other tools.
- RAG Episode 5’s
retrieve()becamesearchHelpCenter()with two tweaks: a configurable minimum score and lean results. - A search tool’s description should list what the documents cover and when to search, including situations other tools miss.
- Keep the layers separate: code enforces standard rules, the knowledge base documents exceptions, humans decide exceptions, and the model handles the conversation.
- Citations survive because every search result carries its
source.
Next, Part 6: Memory: Conversations That Remember. Right now every question starts from zero. If the customer says "and what about the other order?", Nimbus has no idea what they mean. We’ll store conversations in MySQL so follow-up questions work.
Frequently Asked Questions
Agentic RAG is retrieval-augmented generation where search is a tool the AI agent chooses to use, instead of a step that always runs first. The agent decides when to search the knowledge base, writes its own search query, and combines the results with other tools such as database lookups.
It’s more flexible: it skips searching when a question is about live data, can search more than once, and can combine documents with actions. It costs an extra model decision per step, so for a simple FAQ bot, fixed RAG is cheaper and perfectly good.
Yes. Your retrieval function becomes the body of a tool. Wrap it in a tool definition with a clear description, return only the fields the model needs, and make sure "nothing found" is returned explicitly so the agent can say it doesn’t know.
Include the source (such as the file name) in every search result the tool returns, and tell the model in the system prompt to cite it. The model sees the source next to each passage and can reference it in the answer.
Rules that must always be applied the same way, like a 14-day refund window, belong in code. Exceptions and explanations can live in documents the agent searches. Decisions about exceptions that involve money should go to a human.
Full code for this part: GitHub → Gemini Setup/part-05 · OpenAI Setup/part-05
